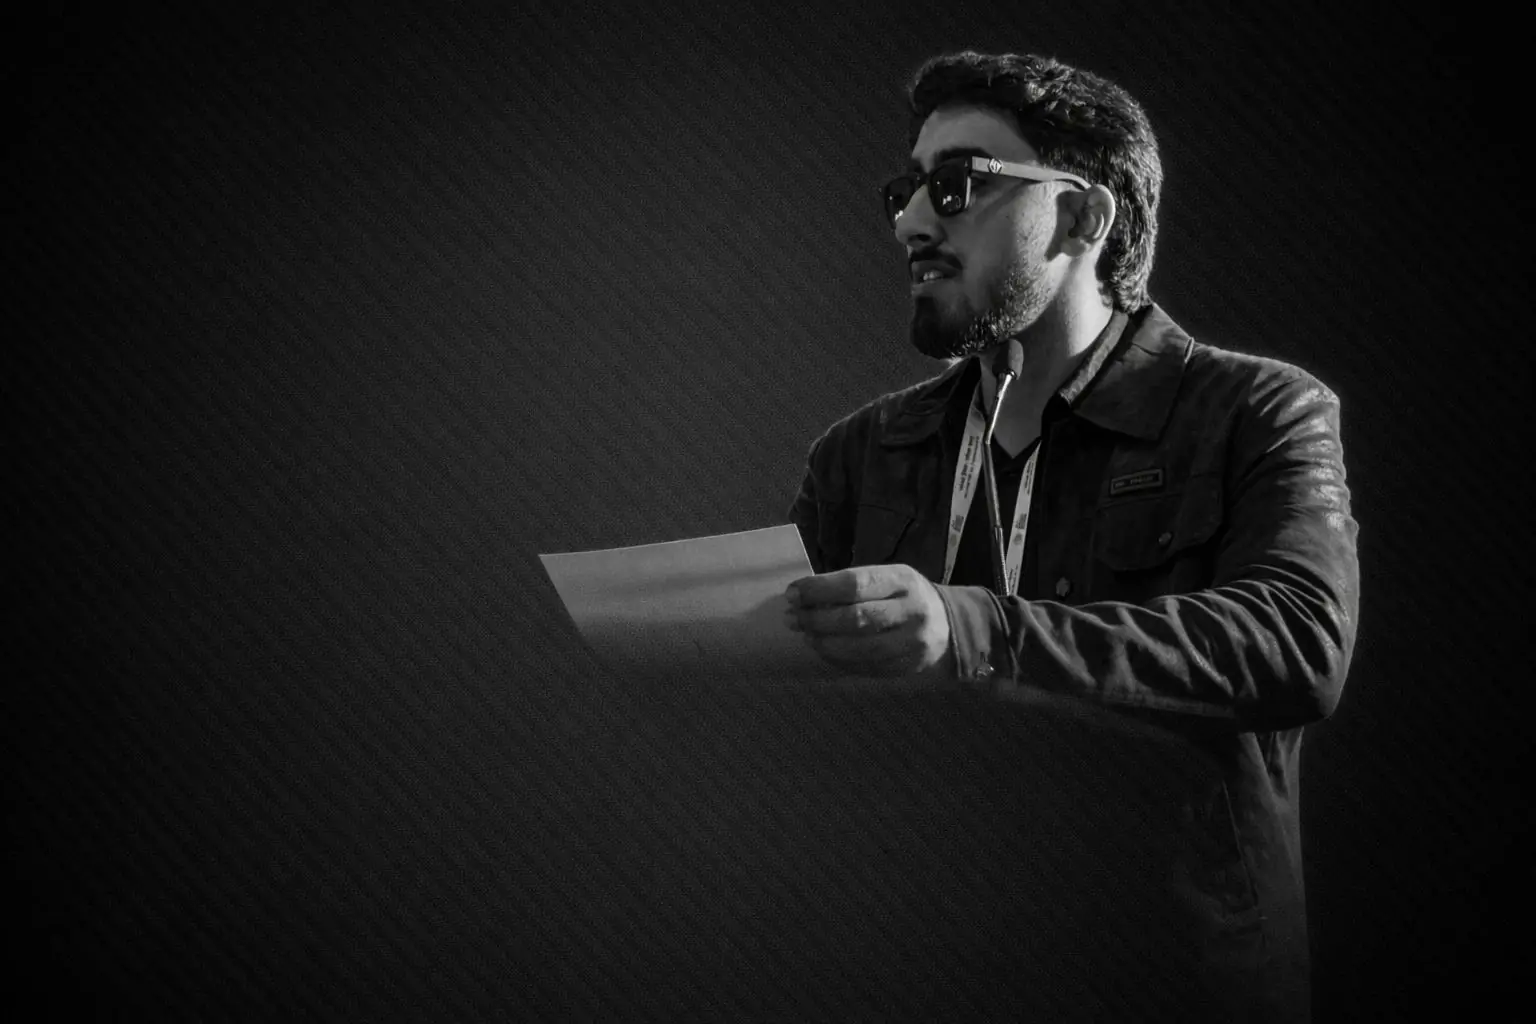
Portfolio
Faizan.
AI Engineer  ·  Builder  ·  Researcher
Faizan Iqbal
Available · CSE Student · India
Faizan.

Building AI systems, full-stack products and research that solve real problems.

From the first specialized Kashmiri LLM to a 28.5M-sample Indic OCR dataset and products with real users, I work where AI research meets software engineering.

CS Engineering student · AI Engineer · Full-Stack Builder

📍 India 🎓 CSE Student ⚡ Open to Opportunities
Featured on Brut India
faizan ~ /profile
$cat profile.json
{
"flagship":"KoshurAI · first specialized Kashmiri LLM",
"research":"4 arXiv papers · cs.CL · cs.CV · cs.AI",
"datasets":"BhartiOCR · 28.5M pairs · 71 languages",
"products":[
"Groopik · real-time media platform",
"PromptForge · AI prompt agent"
],
"featured_on":"Brut India",
"status":"open_to_work"
}
$
Scroll
4
arXiv Papers
NLP · vision · translation data · LLM evaluation
28.5M
BhartiOCR Samples
Pan-Indic OCR · 71 languages · 18 scripts
22M
BharatSetu Lines
1M sentences x 22 Indian languages
0.698
COMET Score
KS→EN · +0.0241 vs Meta NLLB-200
673K+
OCR Training Samples
KoshurOCR + Koshur Pixel ecosystem
3.5K+
BhartiOCR Downloads
Hugging Face, gated dataset
// 01 · Research

Published work.

Four arXiv papers and an ongoing OCR research program, across NLP, computer vision, translation data and LLM evaluation.

Oct 2026 · arXiv:2610.15705

bharatSetu: A 1M x 22 Bridge for Indic Translation

PublishedCo-author

One million sentences aligned across all 22 scheduled Indian languages, so any language pairs with any other: 462 directed pairs without direct translation data for each one. The translations are machine-generated; the paper proposes confidence and human-correction layers.

Jul 2026 · arXiv:2607.20476 · cs.AI

Benchmarking LLMs on Multi-Sensor Physical Hazard Assessment

PublishedFirst author

68 scenarios, 5 frontier LLMs, 1,800 API calls and a four-axis rubric. Every model handled single-sensor hazards but missed the ones that only appear when several sub-threshold readings combine.

Jun 2026 · arXiv:2606.23144 · cs.CV · cs.CL

Koshur Pixel: A Large-Scale Synthetic OCR Dataset for Kashmiri

PublishedCo-author

613,078 synthetic image-text pairs for Kashmiri Nastaliq OCR, the first large-scale set for the script, built with SynthOCR-Gen and 25+ augmentation strategies across fonts, optical degradation and layout.

Jun 2026 · arXiv:2606.15883 · cs.CL · cs.AI

Koshur Diacritizer: A Byte-Level Sequence-to-Sequence Model for Kashmiri Diacritic Restoration

PublishedCo-author

A ByT5-small model that restores diacritics in Kashmiri text (WER 0.2159, 77%+ native-speaker accuracy), with the first public dataset of 23.7K aligned diacritized sentence pairs. Covered by ETV Bharat.

Nov 2025 to now · Research program

KoshurOCR: Multi-Generation OCR Research Program for Kashmiri Nastaliq

Ongoing program

Five OCR architecture generations over about 11 iterations on roughly 673K samples. The finding: the bottleneck is long-sequence decoding, not visual encoding. Active work is on v5.

// 02 · Featured Projects

Work that matters.

Nine systems, datasets and benchmarks. Each one starts from a real gap and ends in something you can open.

Language AI01
2.8MKashmiri tokens
Gemma 3pretrain
16K+translation pairs
NLLB-200 600M
KoshurAI
+0.0241
COMET on FLORES-200, higher in both directions

KoshurAI

Kashmiri translation

Most Kashmiri writing is locked inside old InPage files. I unlocked it, taught a model the language, then tested it against Meta's translator. It scored higher in both directions.

2.8M tokens16K+ pairs+0.0241 COMET
Language AI02
r
72
e
65
s
73
u
75
m
6D
e
65
ByT5 reads the bytes, writes them back with marks
r
é
s
u
m
é
Same idea, shown in English: resume becomes résumé

Koshur Diacritizer

Puts the marks back

Kashmiri is often typed without its small marks, so one spelling can mean several things. The model reads the raw bytes and writes the text back with the marks restored.

WER 0.215923.7K sentence pairs77%+ native-speaker accuracy
Language AI03
1Msentencesx 22 languages
462directed pairs
Hindi
Kashmiri
Tamil
Bengali

BharatSetu

22 languages, any to any

One million sentences, each written in all 22 Indian languages and lined up row by row. So any language can be paired with any other: 462 directions from a single dataset.

1M sentences22 languages462 pairs
Vision AI04
BhartiOCRनमस्ते भारतவணக்கம்নমস্কারనమస్కారం
cleanblurtiltnoisestains
54 ways to damage a page
28.5Mpairs
71languages
18scripts

BhartiOCR

28.5M OCR pairs

Real scans are messy. I render clean text across 71 languages, then wreck it in 54 different ways, so models learn to read the bad copies too.

28.5M pairs71 languages18 scripts
Vision AI05
v1 CNN
v2 CRNN + CTC
v3 PARSeq
v4 TrOCR
v5 Arabic-TrOCR
Error rate of the CRNN baseline
Clean print
10.0%
Printed book pages
18.5%
Degraded historical
49.8%

KoshurOCR

5 model generations

I kept swapping in stronger models until it read better. The baseline copes with clean print and falls apart on old, dirty pages. That gap is the whole problem.

5 generations11 iterations673K samples
Vision AI06
Corpus
Fonts
Layout
Age
Validate
613,078synthetic image-text pairs
25+augmentation strategies

Koshur Pixel

Synthetic pages

A page is built the way a print shop does it: pick the text, pick a font, lay it out, age it, check it. Over 600 thousand pages, none of them scanned by hand.

613K pairs25+ augmentationsfirst large set for Nastaliq
Evaluation07
danger line
Temp
Gas
Smoke
Together
Hazard
5 frontier LLMs tested
Single-sensor hazard
Readings that only add up

PhysicalHazardBenchmark

Do LLMs spot danger?

Each sensor alone looks safe. Add the three together and the room is in danger. I test whether AI models notice the danger that only shows up when readings add up.

68 scenarios5 LLMs1,800 API calls
AI Systems08
Realtime sync + CDN
You
Friend
Friend
no sign-up
files via CDN

Groopik

Live photo rooms

Someone drops a photo into a room and everyone in it sees it instantly. No app, no sign-up. The server passes it along and the files come from a fast CDN.

Live in productionno sign-upzero-egress storage
AI Systems09
make me a landing page, kinda dark, maybe pricing
Who is it for?
Founders
1 Layout  2 Copy  3 Pricing  4 Polish
Router
Llama 3.3 70B
Claude Sonnet

PromptForge

Messy idea to clean prompts

You describe what you want in a messy sentence. It asks a few questions, then hands back clean, ordered prompts and sends each job to the model that suits it.

voice or text3 to 5 questions2 models routed
1 · Language AI
Project 01 · Language AI · Research
KoshurAI
Specialized Neural Machine Translation for Kashmiri

About 7 million people speak Kashmiri and almost no language technology existed for it. KoshurAI is a specialized Kashmiri-English translation model on Gemma 3: continued pretraining on a 2.8M-token Kashmiri corpus, then QLoRA fine-tuning on 16K+ bidirectional pairs. It scores higher COMET than Meta's NLLB-200-distilled-600M in both directions on FLORES-200. Presented at AI Impact Summit 2026.

The Problem

Kashmiri is a low-resource language with near-zero representation in modern AI systems. There were no translation datasets, no NLP tools and no language model, which left a whole linguistic community outside the AI wave. Most source text also sits in InPage, a format that general tooling cannot read.

Key Metrics
2.8M
Kashmiri Tokens (pretraining)
16K+
Parallel Pairs (fine-tuning)
+0.0241
COMET vs NLLB-200 · KS→EN
Training Pipeline
InPage Documents→Corpus Curation→Continued Pretraining→QLoRA Fine-tuning→FLORES-200 Evaluation
Tech Stack
PyTorchHugging FacePEFTLoRAQLoRAGemma 3FLORES-200COMET
Project 02 · Language AI · Published Research
Koshur Diacritizer
Byte-Level Diacritic Restoration for Kashmiri · arXiv:2606.15883

Kashmiri text often leaves out diacritics, which makes words ambiguous and hurts every downstream NLP task. Koshur Diacritizer is a ByT5-small seq2seq model that restores them. It is published on arXiv, released on Hugging Face and was covered by ETV Bharat.

The Problem

The same undiacritized Kashmiri spelling can stand for several different words. Tokenizers, translation, search and text-to-speech all get worse without diacritics, and no neural solution existed for Kashmiri.

Key Metrics
0.2159
Word Error Rate
77%+
Native-Speaker Accuracy
23.7K
Aligned Pairs Released
Model Pipeline
Undiacritized Text→UTF-8 Bytes→ByT5 Encoder→ByT5 Decoder→Diacritized Output
Tech Stack
ByT5-smallPyTorchHugging FaceSeq2Seqjiwer · DER · WER
Project 03 · Language AI · Published Research · Co-authored
BharatSetu
A 1M x 22 Bridge for Indic Translation · arXiv:2610.15705

One million sentences, aligned line by line across all 22 scheduled Indian languages. Every row carries the same meaning in every language, so any language can be paired with any other: 462 directed pairs, with no need for direct translation data for each pair.

The Problem

Most Indian languages have no direct translation data with each other, so something like Marathi to Kashmiri or Bodo to Dogri normally has to detour through English. BharatSetu builds the shared layer once, so every pair is available from the same table.

Key Metrics
1M
Sentences
22M
Aligned Lines · 22 Languages
462
Directed Language Pairs
Data Flow
1M English Sentences→Translated to 22 Languages→Aligned Rows→Any-to-Any Pairs
Tech Stack
Pythonsarvam-translateHugging Face DatasetsParallel Corpora
Any language to any language
Marathi→Kashmiri

Co-authored with Haq Nawaz Malik and Nahfid Nissar. Translations are machine-generated, not human-verified; the paper proposes confidence and human-correction layers on top.

2 · Vision AI and Data
Project 04 · Vision AI · Dataset · New
BhartiOCR
Pan-Indic Synthetic OCR Corpus · 28.5M image-text pairs

A synthetic document-OCR corpus covering 71 languages and 18 writing systems, from the 22 scheduled languages to regional, tribal and classical ones. Built and released by me on Hugging Face, with 3,500+ downloads.

The Problem

Many Indian scripts have very little OCR training data, and Chakma, Lepcha, Limbu, Santali and Meetei Mayek have almost none. Real scans are costly to label and complex scripts need correct shaping, so BhartiOCR renders every sample through a proper text-shaping engine instead of pasting glyphs.

Key Metrics
28.5M
Image-Text Pairs
71
Languages
18
Writing Systems
Generation Pipeline
Text Sources→Unicode + Font Gates→HarfBuzz Shaping→FreeType Rendering→Degradation→WebDataset Shards
Dataset Engineering
134 open fonts54-operator degradation library5,700 shardsWord · line · paragraph · page tiersToken-level boxes
Tech Stack
PythonHarfBuzzFreeTypeWebDatasetHugging Face HubResNet-BiLSTM-CTC
71 languages · 18 writing systems

Synthetic data only. The card lists open limits: no separate validation or test shards yet, and lossy WebP images.

Project 05 · Vision AI · Research Program
KoshurOCR
5-Generation OCR Research Program for Kashmiri Nastaliq

Five architecture generations over about 11 experimental iterations on roughly 673K training samples: the road from a CNN baseline to foundation-model OCR, and the discovery that redirected the whole program.

The Journey → The Finding

Each generation ruled out an architecture family: CNNs lacked sequence understanding, CTC plateaued on ligatures, PARSeq did not generalize to Nastaliq and TrOCR hit tokenizer limits. Custom evaluation (CER, WER, prediction coverage, decoder-length analysis) showed the real limit: decoder sequence collapse, not encoder capacity. The encoder learns Kashmiri glyphs; the decoder truncates long sequences.

Key Metrics
5
Architectures Benchmarked
10+
Experimental Iterations
670K+
Total OCR Samples
Research Timeline
v1 · CNN→v2 · CRNN + CTC→v3 · PARSeq→v4 · TrOCR→v5 · Arabic-TrOCR
Released Baseline
CRNN baseline: 9.7M parametersCER 10.0% clean printCER 18.5% printed book pagesCER 49.8% degraded historicalUnicode normalizationCurriculum learning
Tech Stack
PyTorchTrOCRViTYOLOv8BiLSTM · CTCOpenCVHugging Face
View on GitHub ↗Baseline model on HF →Dataset on HF →⚡ v5 active · decoder-collapse remediation
Project 06 · Vision AI · Published Dataset · Co-authored
Koshur Pixel
Large-Scale Synthetic OCR Dataset · arXiv:2606.23144

The first large-scale synthetic OCR dataset for Kashmiri Nastaliq: 613,078 image-text pairs generated with the SynthOCR-Gen framework and published on arXiv. It is the data side of the KoshurOCR program.

The Problem

OCR for low-resource scripts is limited by data more than by architecture. Hand-labelling Nastaliq does not scale, because contextual ligatures make character-level labels slow and error-prone. Synthetic generation is the only route to scale.

Key Metrics
613K
Image-Text Pairs
25+
Augmentation Strategies
3
Granularities · Word / Line / Page
Generation Pipeline
Corpus Sampling→Font Rendering→Layout Engine→Augmentation→Validation
Tech Stack
SynthOCR-GenPythonPillow · OpenCVfonttoolsKS-PRET-5M corpus
3 · Evaluation & Benchmarking
Project 07 · Evaluation · Published Research · First Author
PhysicalHazardBenchmark
Benchmarking LLMs on Multi-Sensor Physical Hazard Assessment · arXiv:2607.20476

Can frontier LLMs read sensor data and reason correctly about physical danger? A 68-scenario benchmark of 5 frontier models across toxic gas, thermal, mechanical, intrusion and deliberately ambiguous cases, scored on four axes over 1,800 API calls.

The Problem

LLMs are being wired into industrial monitoring, smart buildings and robot safety systems, yet no public benchmark tests whether they can turn multi-sensor readings into the right hazard call and the right action. Existing benchmarks test academic reasoning, not physical-world judgment.

Key Metrics
68
Scenarios
1,800
API Calls · 5 Frontier LLMs
4
Evaluation Axes
Evaluation Pipeline
Sensor Context→LLM Under Test→Hazard Classification→Action Check→Coherence Score
Finding

Every model handled single-sensor hazards well but missed hazards that only appear when several sub-threshold readings add up.

Tech Stack
PythonBenchmark Design5 provider APIsStructured rubrics
4 · AI Systems
Project 08 · AI Systems · Live Product
Groopik
Real-time Media Sharing Platform · groopik.com

A real-time, room-based photo sharing platform: no install, no sign-up, anonymous sessions and a gallery that updates live for everyone in the room. Supabase Realtime handles sync and Cloudflare R2 handles zero-egress media storage.

The Problem

Group media tools are heavy, slow and built around accounts. Groopik is built for the moment at an event: scan, join a room, upload, see everyone's photos. Real users then exposed real problems, and each got a fix: stale-while-revalidate caching for CDN lag, client-side rate limiting for upload bursts, and chunked resumable uploads for weak event Wi-Fi.

Key Decisions
0
Sign-ups or Installs
Live
Realtime Gallery Sync
3
Production Fixes Shipped
Architecture
Next.js Client→Supabase Realtime→Cloudflare R2→CDN Delivery
Tech Stack
Next.jsSupabaseCloudflare R2TypeScriptPostgreSQLTailwind
Project 09 · AI Systems · Product
PromptForge
Multi-Model Prompt Engineering Assistant

A voice-first assistant that turns a vague request into a precise, structured prompt. It asks 3 to 5 clarifying questions first, then routes the job between Llama 3.3 70B and Claude Sonnet depending on the task.

The Problem

Most people get weak answers from LLMs because the prompt is vague, not because the model is bad. PromptForge fixes quality at the input: voice or text in, clarification, then a decomposed set of ordered, self-contained prompts out.

Core Features
🎙️
Voice Input
🔄
3 to 5 Clarifying Questions
🧭
Rule-Based + LLM Routing
Workflow
Voice / Text Input→Intent Analysis→Clarification→Routing by Task→Ordered Prompts
Tech Stack
ReactGroq · Llama 3.3 70BAnthropic ClaudeWeb Speech APIVercel FunctionsTypeScript
// 03 · Achievements

Built to compete.

Summits, national podiums, state titles and open-source work. Newest first.

May 2026 · Open Source
Contributor, GirlScript Summer of Code 2026
AI and agent projects: feature work, structured training data and code reviews
🌱 Open Source
Feb 2026 · AI Research
University Representative, AI Impact Summit 2026
Presented 15 AI projects · Featured by Brut India
🤖 AI Research
Dec 2025 · Recognition
University Representative, Startup Punjab Conclave 2025
Presented products at state level · Met the Chief Minister of Punjab
Oct 2025 · Research
Runner-up, Project-O-Research, LPU
School of Computer Science
🔬 Research
Since Apr 2025 · Leadership
Outreach Head, RISC Robotics Club, LPU
Industry outreach and partnerships, including the Indian Army · 30+ certificates from IITs, NITs and corporates
Mar 2025 · Robotics
Rank #1, IIT Mandi Xpecto'25
1,000+ participants
🥇 National Winner
Feb 2025 · Writing
Winner, National Space Day writing competition
ISRO
Jan 2025 · Robotics
3rd Place, IIT Jodhpur Prometeo'25
National robotics combat · Built the bot, competed, placed
🥉 National Podium
2022 to 2024 · Athletics
3x J&K State Wushu Champion
Three consecutive titles · Discipline and physical consistency
🥊 3x Champion
Feb 2024 · Robotics
Winner, RC-Xtreme 3.0 Robotics Competition
Remote-controlled systems · Speed, precision, engineering
🏆 Champion
// 04 · Tech Stack

Tools of the trade.

From raw text to a live product: the tools, in the order I reach for them.

01

Make the data

Turn text into millions of training images.

🧪Synthetic Data Generation🔡HarfBuzz✒️FreeType🔠fonttools🖼️Pillow👁️OpenCV📦WebDataset📊Datasets API
02

Train

Teach models a language or a script.

🐍Python🔥PyTorch🖥️CUDA🧠Transformers🤗Hugging Face🧩PEFT🔄LoRA⚡QLoRA💎Gemma 3🔤ByT5👁️TrOCR / ViT🎯YOLOv8📈Weights & Biases
03

Measure

Check them against real benchmarks.

🎯COMET🌐FLORES-200📐CER / WER / jiwer
04

Build

Wrap the model in a product people use.

⚛️React▲Next.js🔷TypeScript💨Tailwind CSS📦Vite🌐HTML5🎨CSS / Sass🟢Node.js🚂Express🐘PHP🔌REST APIs🔑JWT / Auth🧪Postman
05

Ship

Store it, deploy it, keep it live.

⚡Supabase🐘PostgreSQL🍃MongoDB🔴Redis📊SQL🐳Docker☁️AWS🌩️Google Cloud▲Vercel🔶Cloudflare R2
Off the screen
🤖Arduino⚙️Embedded C📡IoT Protocols🔌Raspberry Pi🛠️Circuit Design
// 05 · Current Focus

What's being built.

Active engineering threads right now.

👁️

KoshurOCR v5

Fixing decoder sequence collapse in Nastaliq OCR with length-aware decoding objectives and short-to-long curriculum learning over the 673K-sample ecosystem.

Active
📚

BhartiOCR benchmarks

Running the first recognition benchmarks on the 28.5M-sample corpus (ResNet-BiLSTM-CTC on Hindi, Bengali, Tamil and Urdu) to separate the effect of degradation from typography and layout.

In progress
🎙️

Koshur Knowledge Assistant

Speech and RAG over the Kashmiri corpus: the next piece of the Kashmiri AI stack, building on KoshurAI, the Diacritizer and OCR.

🔬 Prototyping
🌱

Open Source & Products

Contributing to AI and agent projects through GirlScript Summer of Code 2026, while improving Groopik and PromptForge from real user feedback.

Shipping
// 06 · About

From Kashmir,
building for the world.

I'm a builder from Kashmir who likes solving hard problems with AI, full-stack software and product engineering. I don't build things for the sake of building. Every project starts with a clear problem and ends with something measurable.

From the first specialized Kashmiri LLM to a 28.5M-sample Indic OCR dataset, four arXiv papers and products with real users, I focus on work that makes a measurable difference for real people.

I'm equally at home training a model on CUDA, designing a PCB for a combat robot, or architecting a backend. That range is what I bring to a team. I learn fast, adapt quickly, take the lead when it is needed and think a problem through before I touch the code.

Interests
  • 🧠AI Research & LLM Fine-Tuning
  • 🤖Robotics & Embedded Systems
  • 🌍Low-Resource & Multilingual AI
  • ⚙️Product Development
  • 🏗️Systems Architecture

// Profile

LocationIndia 🇮🇳
ProgramB.Tech CSE · 2027
UniversityLPU
FocusAI Research + Full-Stack
StatusOpen to Work ✓
Emailifaizan041@gmail.com

// Experience

Open Source Contributor
GirlScript Summer of Code · May 2026
Web Development Intern
GetInterned · Nov to Dec 2025
Outreach Head
RISC Robotics Club, LPU · Apr 2025 to now
// 07 · Beyond Software

Same engine.
Different arena.

The discipline that wins Wushu championships is the same discipline that ships code at 2am.

🥊

3x Wushu Champion

J&K State Level

🤖

Robotics Competitor

National IIT Podiums

🎤

Public Speaker

AI Summits & Events

🔬

Research Presenter

15 AI Projects Shown

🏹

Outdoor Pursuits

Archery · Football · Swim

// 08 · In the Press

Work that gets noticed.

Press and partnerships that came from the work.

2026

National Media Feature

Featured by Brut India as a university representative at AI Impact Summit 2026, presenting 15 AI projects.

2026

National Press: Kashmiri AI Research

"Three Kashmir Engineers Develop AI Tool to Preserve Native Language in Digital Age", covering our Kashmiri language AI work (KoshurAI and Koshur Diacritizer).

Ongoing

RISC Robotics Club Collaboration

Coordinated robotics outreach with the Indian Army through the RISC club as Outreach Head, LPU.

// 09 · Certifications

Verified credentials.

30+ certificates from recognized platforms. A selection of the most relevant.

NPTEL
Privacy & Security in Online Social Media
Nov 2025
Verify ↗
LPU
Data Structures and Algorithms
July 2025
Verify ↗
Coursera
Fundamentals of Network Communication
Nov 2024
Verify ↗
IBM
Introduction to Hardware and Operating Systems
Sept 2024
Verify ↗
FreeCodeCamp
Responsive Web Design
Sept 2023
Verify ↗
GLA University
Data Science Foundations
Aug 2023
Verify ↗